HeyGen
How a leading AI video platform unlocked new product capabilities by replacing expensive managed providers with a single, cost-effective inference API.
Train, fine-tune and serve on bare-metal NVIDIA GPU clusters or serverless GPU compute, from data centers Runware builds and owns. Published pricing, InfiniBand on Blackwell, no egress fees.
H100s are up to 60% cheaper on Runware than on CoreWeave. RTX PRO 6000s up to 75%, H200s up to 52%, B200s up to 36% and L40S GPUs up to 56%. On demand, with no commitment, every GPU in the table is 20 to 36% less.
Prices checked 22 Oct, 2026.
What 730 hours on a single H100 costs per month, at the list rates in the table above. Reserve a baseline and burst above it on Serverless to land between the two Runware figures.
Years of land, permits and construction, then GPUs financed on top. All of that overhead ends up in the hourly rate. When the market asks whether that still adds up, it is your capacity on the line.
So we rebuilt the stack. A Sonic Pod is a complete 1 MW AI data center in a 20 ft container: built in three weeks, set on a pad where power is cheap, live in days. No hundred-acre building, no overbuilt redundancy, no cloud provider's margin in the rate. Leave CoreWeave and you land on infrastructure we own, run and keep building.
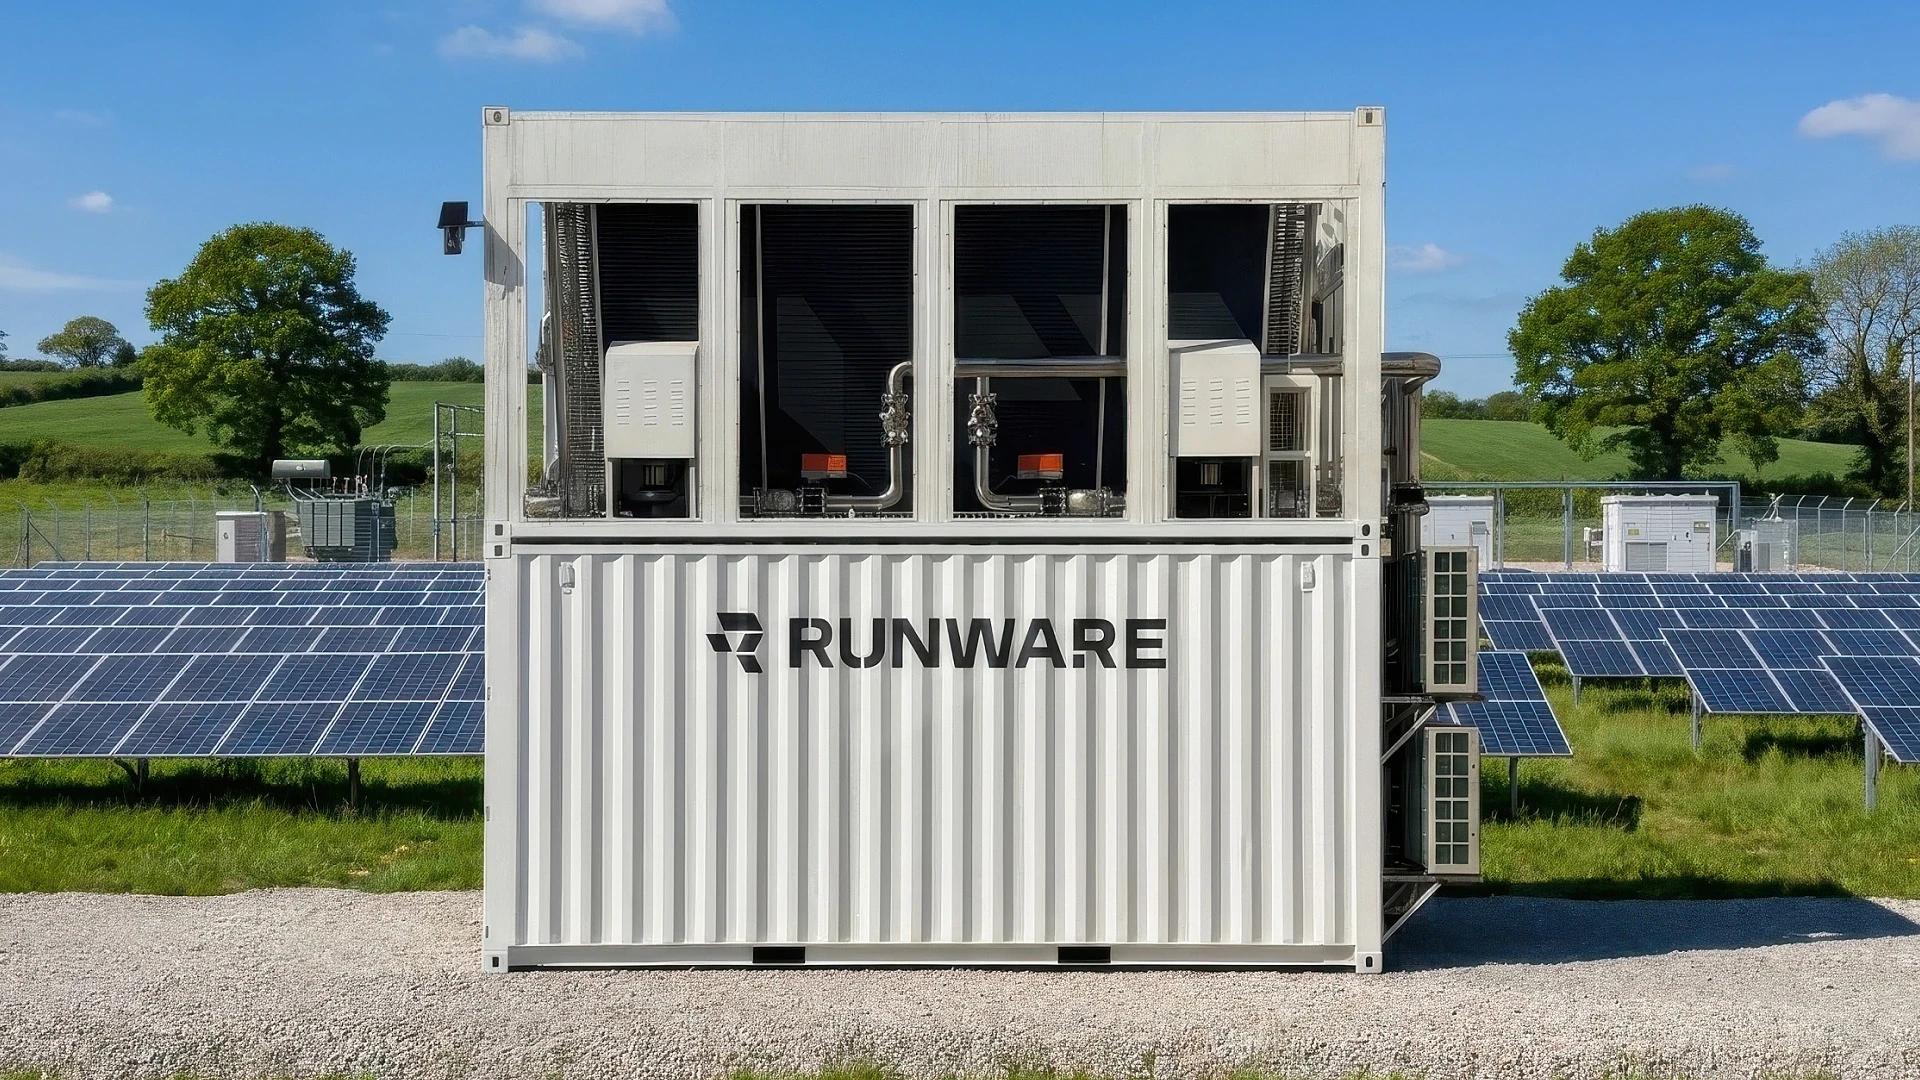
Same NVIDIA GPUs, same bare-metal access, same InfiniBand. The difference is the building: Runware designs and owns its Sonic Pod data centers, so there is no leased facility and no cloud margin in the GPU-hour.
Nothing to port. Your Kubernetes or Slurm runs on our bare metal as is. The containers you serve become Serverless apps. Storage moves to WEKA.
Same stack, on GPU nodes reserved for the term. InfiniBand on B300 and NVL72.
Bring the container, pick the GPUs, set the worker limits.
Single-tenant, all-NVMe, same term as the GPUs, no egress fees.
Lower bill, no GPU platform to run. Here's what moving to Runware looked like for teams shipping at production scale.
How a leading AI video platform unlocked new product capabilities by replacing expensive managed providers with a single, cost-effective inference API.
How OpenArt achieved sub-second image generation at scale with Runware's Sonic Engine.
How a fast-growing video generation startup deployed a major model release in hours.
How NightCafe scaled their AI art community without hiring a single infrastructure engineer.
Yes. CoreWeave sells bare-metal HGX instances on Kubernetes, SUNK for Slurm, committed-use contracts and an inference platform. We sell bare-metal GPU nodes and clusters, and serverless GPU compute, on data centers we build ourselves. Same hardware, different building, lower rate.
On demand, Runware is 20 to 36% cheaper than CoreWeave across the 5 GPUs both price; reserved, 36 to 75%. An H100 is $6.16 per GPU-hour on CoreWeave, $3.95 on Runware on demand and $2.45 reserved. CoreWeave's figures are from its 8-GPU HGX instance prices, divided by eight (North America), checked 22 Oct, 2026. Runware's are the Serverless rate card, billed by the second.
One. Serverless workers come in 1, 2, 4 or 8 GPUs. Bare metal comes as the hardware does: a 4-GPU RTX PRO 6000 server, an 8-GPU HGX B300 server or a 72-GPU GB300 NVL72 rack, interconnected across pods for larger clusters. See GPU Compute.
No. Most GPU clouds rent the data center and finance the GPUs. We design, build and run our own Sonic Pods, on 600 MW+ across the US and 2 GW+ across Europe. Your reservation sits on hardware we own, and we build the next pod when you need it. See Sonic Pods.
Yes, on bare metal. Run the stack you run on CoreWeave today on our GPU nodes and clusters, with InfiniBand on B300 and NVL72. Serverless is the other option: we run the workload, so there is no shell into a worker. See GPU Compute.
Serverless: reserve a number of GPUs of one type for one to 24 months. They stay yours when the shared pool is full, and anything above the reservation runs on pay as you go. Bare metal: two, three or four year terms, priced by upfront share, confirmed when the order is signed. Hardware, software, support, power and operations are all included.
Serverless runs in us-east, us-west, eu-west and eu-central. Bare metal sits on Sonic Pod sites across four US and five European locations, and you choose the site when you reserve. See Sonic Pods.
Reserve serverless capacity from one GPU at $0.63 per GPU-hour for 1 to 24 months, or talk to an engineer about bare-metal HGX B300 and GB300 NVL72 clusters: hardware, site, term and delivery date.