GPU compute.
Half the cost.
Bare-metal GPU clusters and serverless GPU compute on Sonic Pods across the US and Europe. Up to half the typical cost of a hyperscaler, powered by modular infrastructure built from the ground up for AI.
Hardware on offer
HGX B300
8-GPU HGX server
from$3.43per GPU-hour · reservedAllocating nowGB300 NVL72
72-GPU rack-scale
from$3.62per GPU-hour · reservedAllocating nowRTX PRO 6000
4-GPU server
from$0.63per GPU-hour · reservedAllocating nowVera Rubin NVL72
72-GPU rack-scale
from$5.07per GPU-hour · reservedFrom 2027
Starting rates, based on term and upfront commitment · confirmed at signing
Reserve once. Use it your way.
One capacity reservation, two ways to run. Use bare-metal GPU clusters for workloads you operate yourself, serverless GPU compute for workloads you want us to run, or mix both.
GPU cloud pricing
per GPU-hour.
Two to four year commitments, priced by upfront share, in USD per GPU-hour. Most partners choose three years.
HGX B300
8-GPU HGX server
| Upfront | 30% | 50% |
|---|---|---|
| 2 years | $6.80 | $6.47 |
| 3 years | $4.61 | $4.38 |
| 4 years | $3.66 | $3.43 |
GB300 NVL72
72-GPU rack-scale
| Upfront | 30% | 50% |
|---|---|---|
| 2 years | $7.16 | $6.82 |
| 3 years | $4.85 | $4.62 |
| 4 years | $3.85 | $3.62 |
Vera Rubin NVL72
72-GPU rack-scale
| Upfront | 30% | 50% |
|---|---|---|
| 2 years | $10.01 | $9.53 |
| 3 years | $6.79 | $6.47 |
| 4 years | $5.40 | $5.07 |
RTX PRO 6000
4-GPU server
| Upfront | 30% | 50% |
|---|---|---|
| 2 years | $1.19 | $1.13 |
| 3 years | $0.83 | $0.79 |
| 4 years | $0.67 | $0.63 |
Longer terms and higher upfront commitments reduce the rate. Pricing is confirmed when the order is signed and is subject to hardware availability at deployment. Bare-metal and serverless capacity can also be combined within a single agreement.
Not ready to commit? Serverless pay as you go starts at $1.99 per GPU-hour on RTX PRO 6000, metered by the second. See the serverless rates.
Built on data centers we design and own, and tuned for inference. Reserve GPU capacity for a term and use it as bare metal, serverless, or both, without a hyperscaler margin built into the rate.
That's how reserved GPU capacity comes in at around half the typical hyperscaler cost.
We build
the hardware
Servers, racks, cooling and power designed in-house for inference. Nothing generic to pay a margin on.
We ship the
data center
Pods are manufactured and trucked in, then set on a pad where power is cheap. No permitting path, no hundred-acre building.
You pay less
per GPU-hour
The facilities layer costs a fraction of a traditional build at the same scale, and that difference is in the rate you reserve at.
Benchmark before you reserve.
We run your model as-is on the hardware you would commit to, then work with your engineers to size the cluster and tune the serving path. You see the economics on your workload, not ours, before signing a term.
- Your model benchmarked as-is on the GPUs you would reserve
- Profiling across HGX B300, GB300 NVL72 and RTX PRO 6000 where they fit
- Cluster sizing: GPU count, fabric and storage for the workload
- A clear view of price-performance per GPU-hour before you sign
What every deployment includes.
- Network
- InfiniBand fabric on every B300, GB300 and Vera Rubin cluster, with interconnect across pods for large cluster sizes. RTX PRO 6000 clusters run on standard Ethernet and are built for inference.
- Connectivity
- Redundant internet connectivity at every site.
- Cooling
- High-efficiency hybrid cooling designed for dense GPU workloads, using closed-loop liquid cooling with minimal water consumption in normal operation.
- Operations
- Built and operated by Runware, with 48-hour on-site intervention and 24/7 on-call support.
- Storage
- Single-tenant WEKA parallel file system on all-NVMe nodes, built to the NVIDIA reference architecture for NVL72 clusters. $75 per usable TB per month on a 3-year term, $65 on 4. No egress or transfer fees.
Deployed where the power is.
PV parks, wind sites, industrial campuses and grid-edge locations across the US and Europe. Sonic Pods are modular GPU data centers, set on their pad in a day.
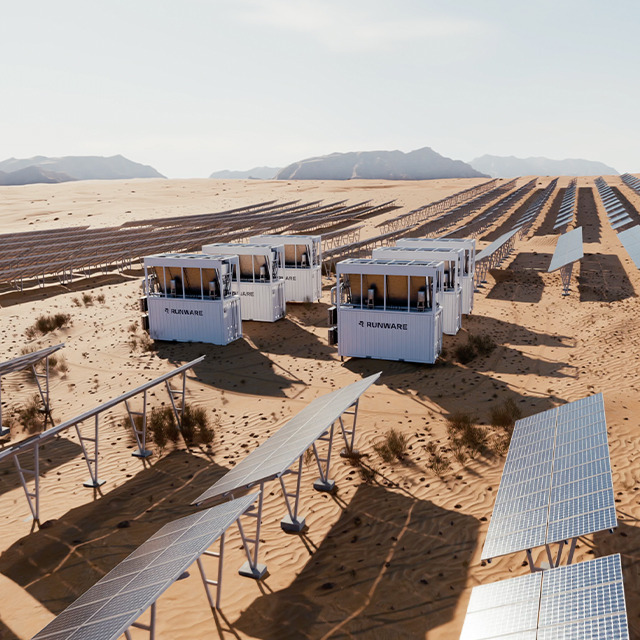
600 MW+
Across 4 sites
- US Central
- US Mid-South
- US Gulf
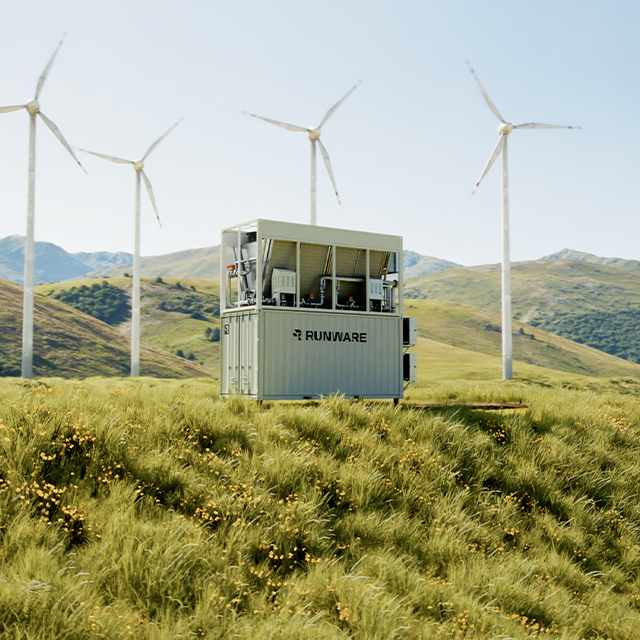
2 GW+
Across 5 sites
- Europe East
- Europe North
- Europe North-East
How to reserve your allocation.
Three steps from a scoped request to a locked delivery window.
- 01Scope
Hardware, site, term and upfront share.
- 02Request
We confirm the allocation, pricing and a delivery window.
- 03Order
Signature confirms the allocation and locks the delivery window.
FAQs
Bare metal when you want dedicated GPU infrastructure and run your own stack on it, from a full 72-GPU rack. Serverless when you want the GPUs guaranteed but the platform run for you, from a single GPU. The same agreement can hold both.
Two, three or four years, with 30% or 50% paid upfront. Longer terms and higher upfront shares lower the per-GPU-hour rate. Pricing is confirmed at order signing, subject to hardware availability at deployment.
HGX B300, GB300 NVL72 and RTX PRO 6000 are allocating now in the US and Europe. Vera Rubin NVL72 allocations start in 2027. The delivery window is fixed in the order form.
Reserved rates are in the cards above: HGX B300 from $3.43 and GB300 NVL72 from $3.62 per GPU-hour on a four-year term with 50% upfront, rising to $6.80 and $7.16 on two years with 30% upfront. Pricing is confirmed at order signing.
Single-tenant WEKA storage on all-NVMe nodes is priced per usable TB per month on the same term and upfront share as the GPUs. Hardware, software, support, power and operations are included, with no egress or transfer fees.
Run on Serverless pay as you go: per-second billing from the shared pool, no term. Reserve later once the baseline is clear.
Reserve capacity
Tell us the hardware, region and term you have in mind, and whether you want it as a dedicated cluster or as guaranteed serverless capacity. We come back with an allocation and a delivery window.