The modular AI data center factory.
Plug-in AI factories, vertically integrated and built on an assembly line, with custom direct-to-chip liquid cooling for every GPU class from RTX PRO 6000 to Vera Rubin. Ten gigawatts a year, shipped anywhere and brought online wherever there’s already power.
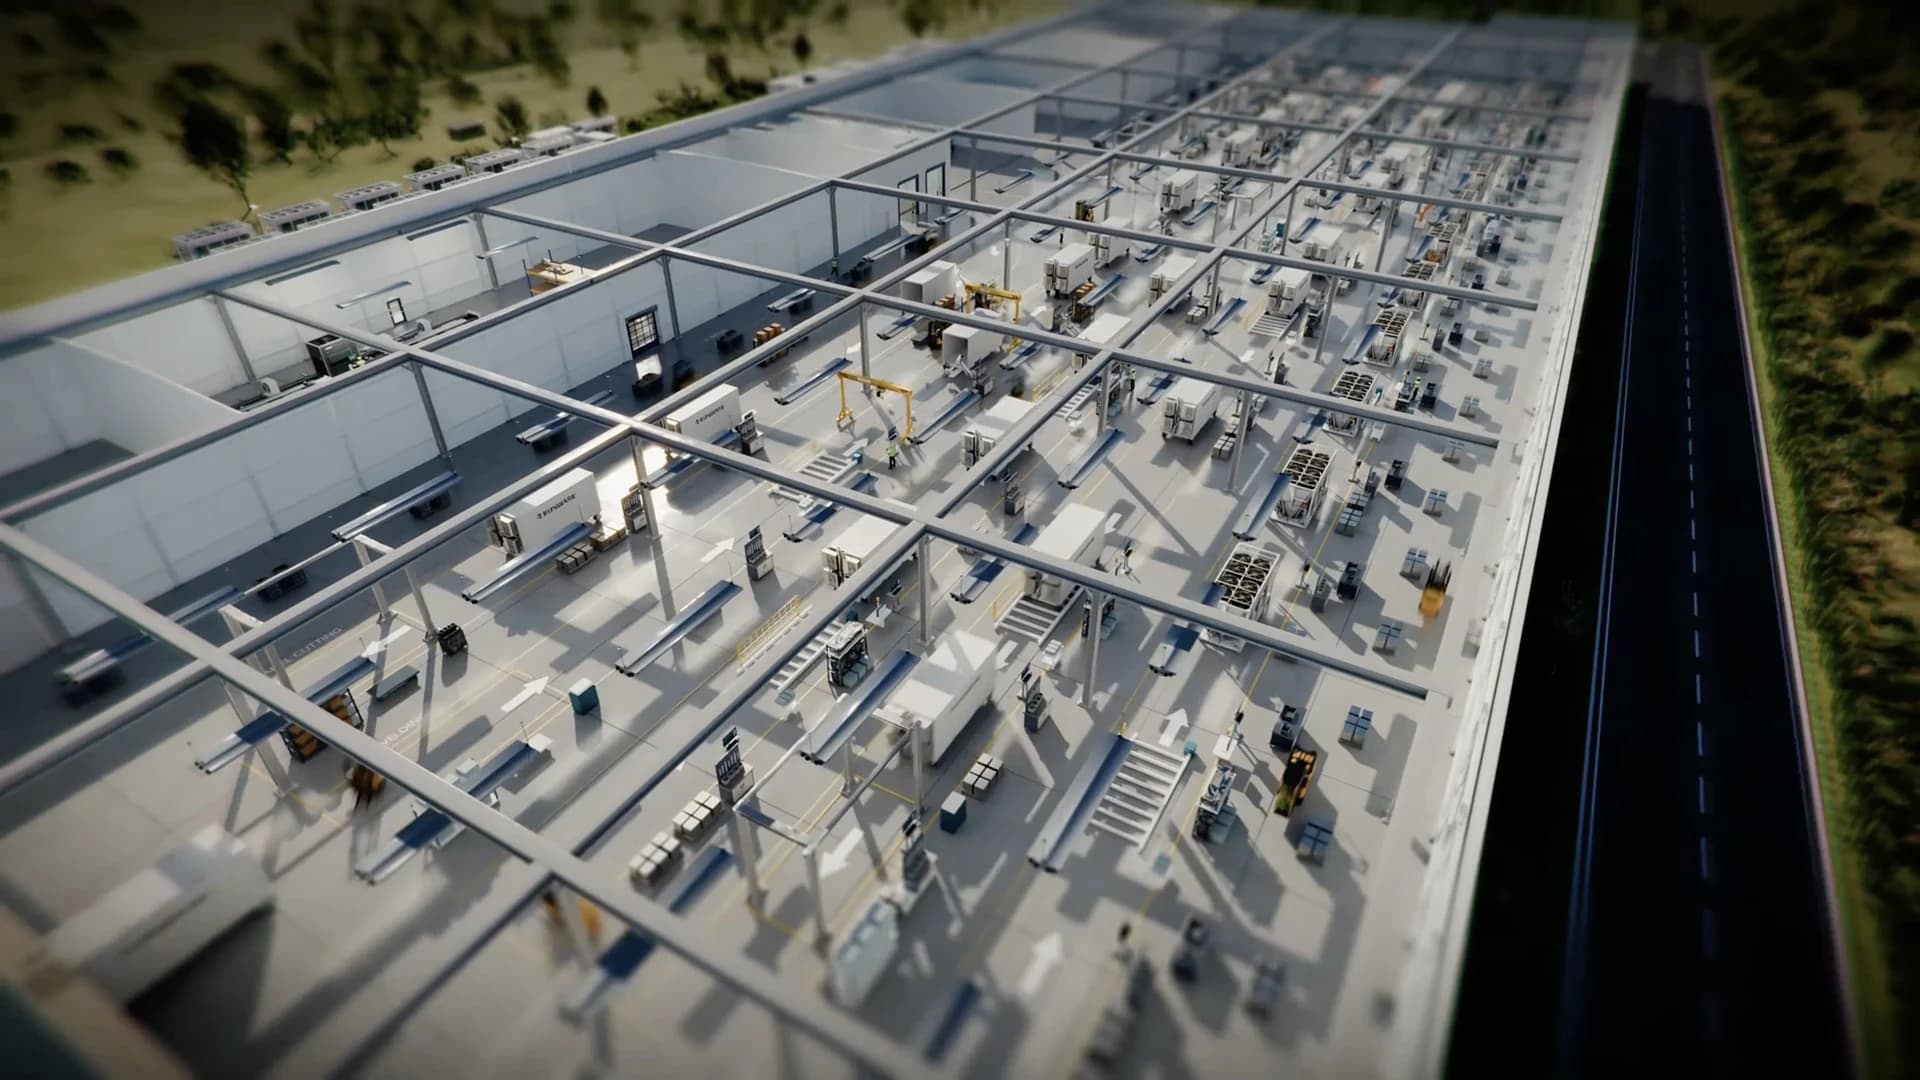
Time to first token: days, not years.
Inference demand is growing faster than conventional data centers can be built, and every new site is gated by grid connection, permits and local opposition. Runware’s AI factory takes construction off the critical path: pods leave the line complete, tested and provisioned, and the site needs only a pad, power and fibre.
$1M
Per usable megawatt per year, pod-only. A conventional build runs $17.6M per megawatt up front
48hours
From delivery to first token, at a site that already has power
Any
Country. Sovereign capacity inside your own borders, close to the data it serves
Zero
Water consumed. Closed-loop cooling, powered by renewables
A data center’s worth of capacity, every 24 hours.
The factory is vertically integrated. The cooling loops, power electronics, PCBs and network switches are designed and built in-house, then fitted pod by pod on one production line, like cars. Every pod is tested at full load before it ships, at up to 30 MW a day.
- Facility
- 50,000 m² in Europe
- Daily output
- Up to 30 MW of pods
- Vertically integrated
- Cooling, power, PCBs, switches
- Before shipping
- Full-load test on every pod
- Logistics
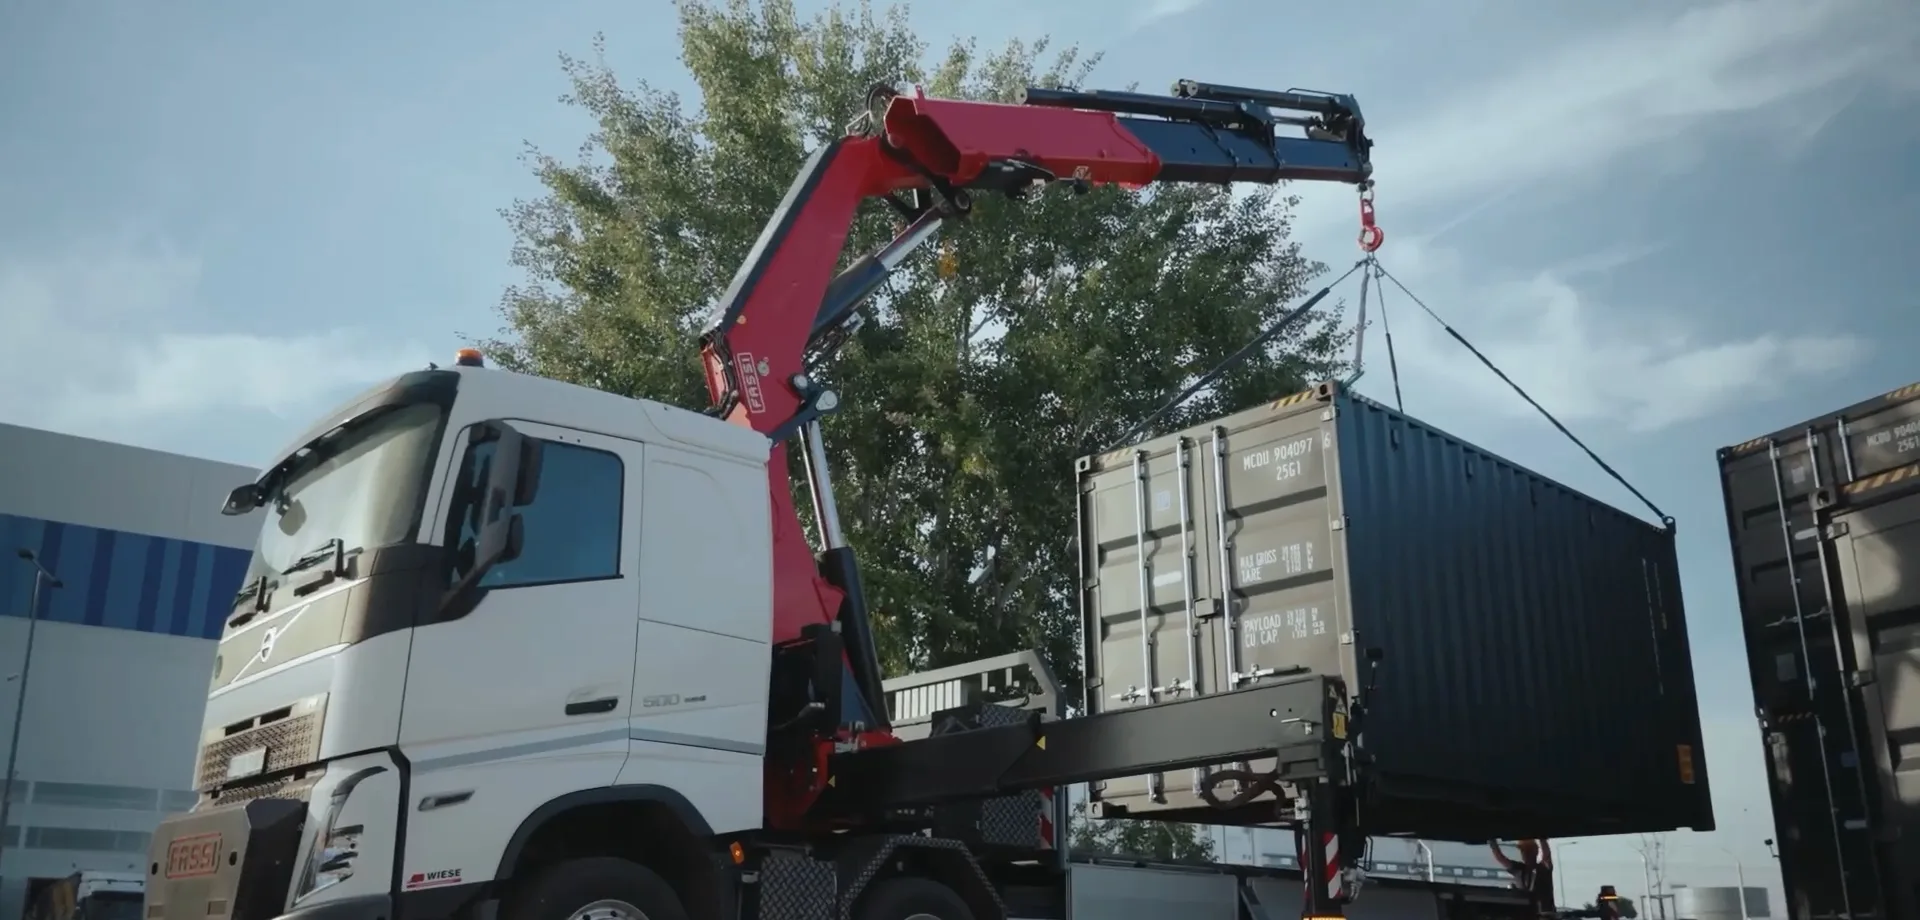
- Road across Europe, sea port for the US
- First units
- Q1 2027
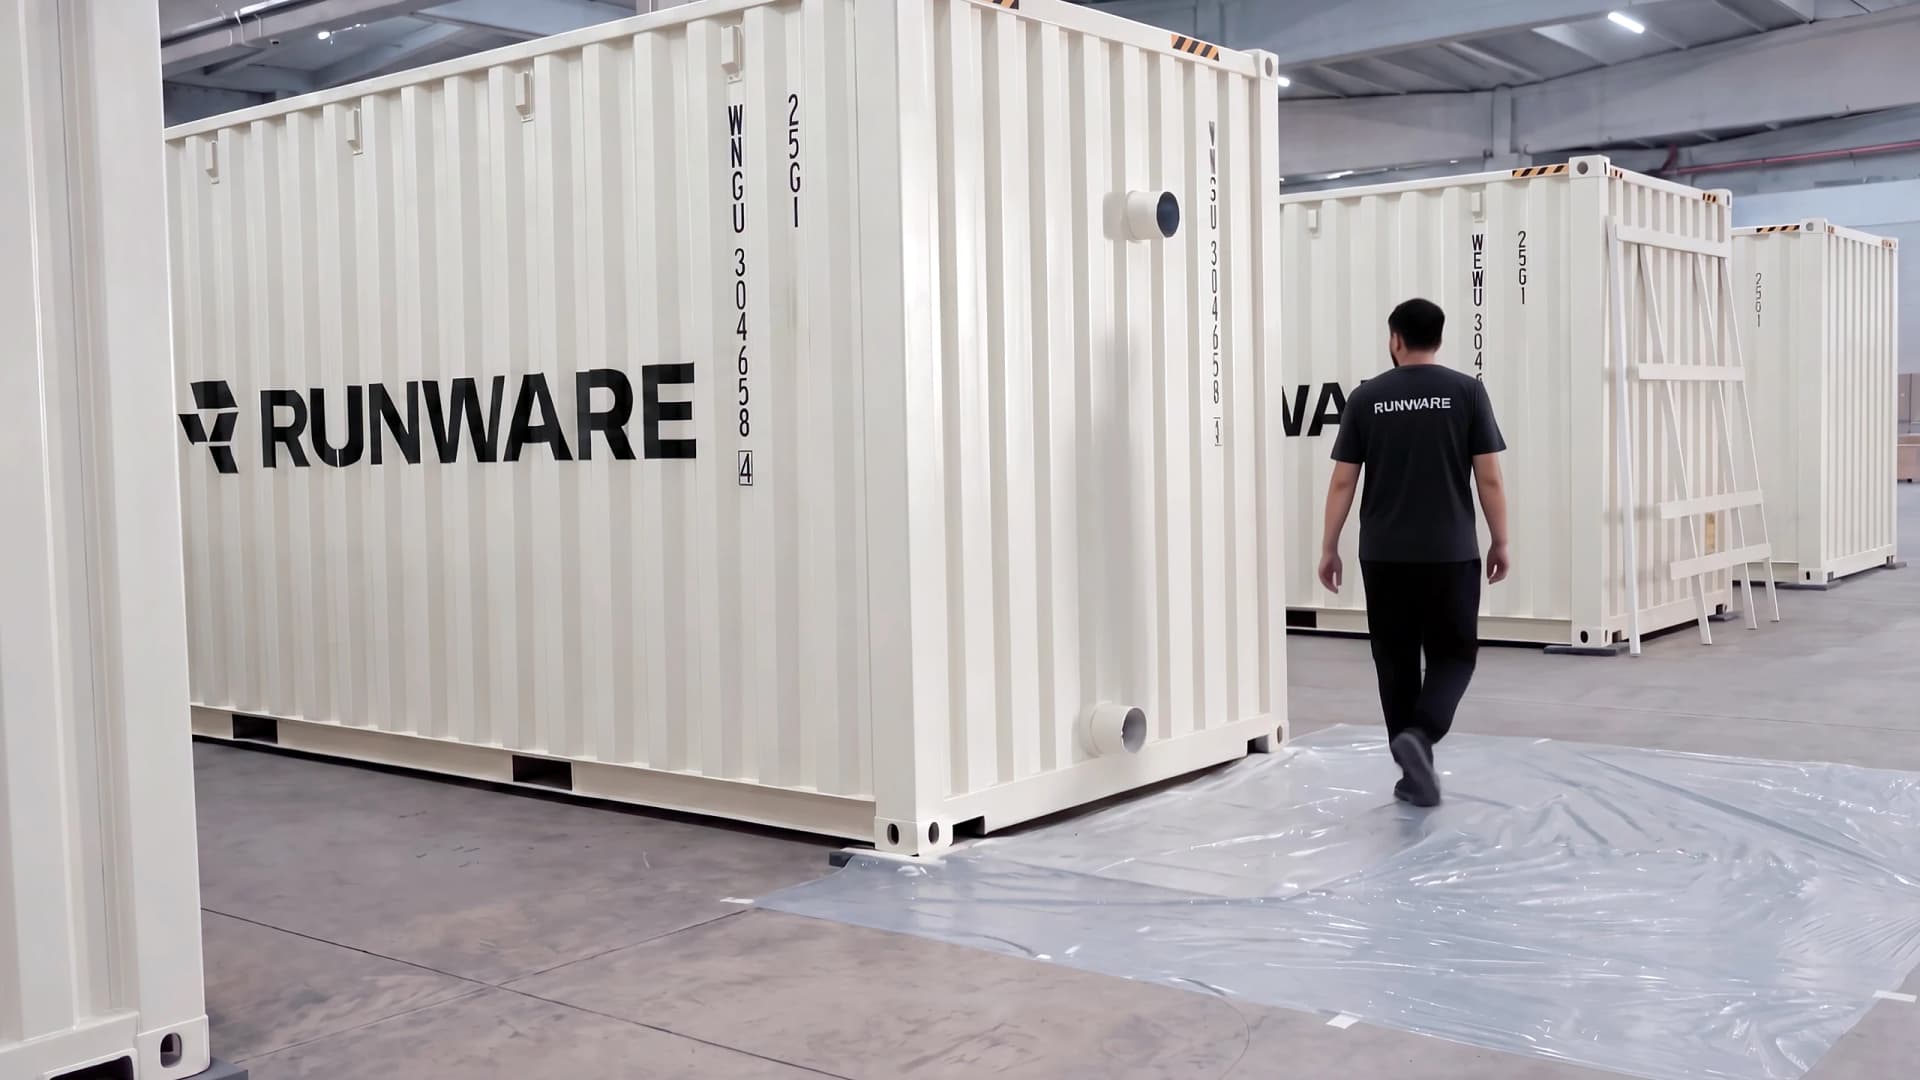
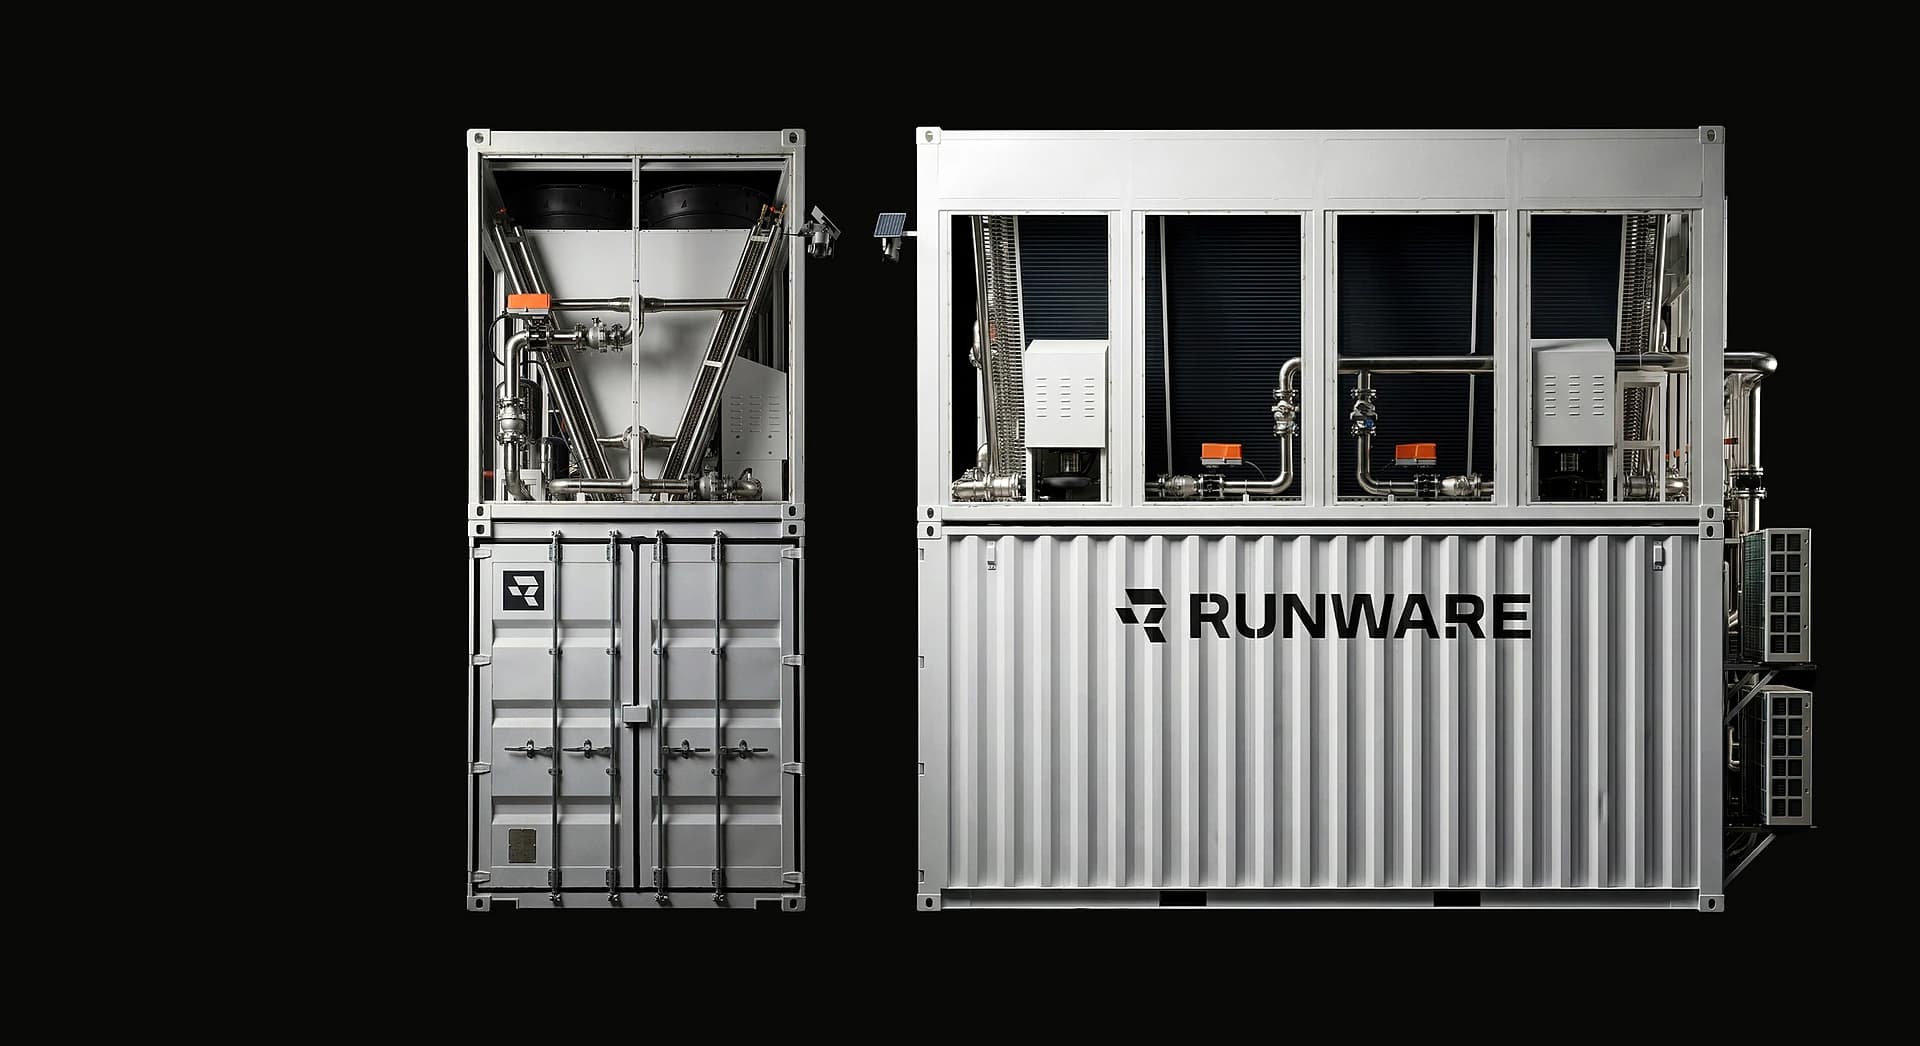
- 20 ft
1 MW
- 40 ft
2 MW
From construction project to manufactured product.
Every data center used to be a one-off build, with its own design, its own site works and years of capital sitting idle. The factory turns it into a standard 1 MW or 2 MW unit, built and tested the same way every time, so capacity arrives on a predictable schedule and GPUs start producing tokens within days of landing.
- One standard unit, built thousands of times over
- Robotic assembly and a full-load test, every time
- Provisioned by software before it leaves the line


Configurable across the entire GPU spectrum.
DSX POD is built around Vera Rubin. Runware’s Sonic Pods carry the same factory-built design across the whole NVIDIA range, with custom direct-to-chip liquid cooling tuned to each platform: frontier racks for training, RTX PRO 6000 for high-volume inference that doesn’t need frontier silicon. No other modular data center is configurable this widely.
Supported configurations
- Reserve capacity
NVIDIA Vera Rubin NVL72
Frontier training · DSX POD · NCP · DGX SuperPOD
Coming online Q1 2027 - Reserve capacity
NVIDIA GB300 NVL72
72-GPU rack-scale, liquid-cooled
Available now - Reserve capacity
NVIDIA HGX B300
8-GPU HGX server, liquid-cooled
Available now - Reserve capacity
NVIDIA B200
8-GPU HGX server
Available now - Reserve capacity
NVIDIA H200
141 GB HBM3e
Available now - Reserve capacity
NVIDIA H100
80 GB HBM3
Available now - Reserve capacity
NVIDIA RTX PRO 6000
High-volume inference, liquid-cooled
Available now
Your site, or one of ours.
From 5 MW to 2 GW campuses, sited where the power is already generated: wind, solar and hydro. No new grid connection, no multi-year permit, and capacity close to the users and data it serves.
- Powered sites secured
- 397MW
- Within six months
- 1.2GW
In production since Q1 2026. 100% uptime.
Runware’s own inference platform has been serving tokens from Sonic Pods all year. Our existing European assembly operation will have built 41 of them by the end of 2026. The factory scales up that same process.
We run the pods we deliver.
One operator from the factory floor to the running cluster: commissioning, 24/7 monitoring, remote hands and maintenance, so you get usable megawatts without hiring a data center team.
Reserve capacity for any AI workload.
Training, inference or a sovereign deployment. Bring your own GPUs or have us supply them, and tell us your region and timeline.
Reserve capacity
Training, inference or a sovereign deployment. Bring your own GPUs or have us supply them, and tell us your region and timeline.